dirty bit가 0인 folio를 보고 disk와 일치한다고 판단하면 진행 중인 writeback을 놓칠 수 있습니다. I/O를 시작하려고 dirty를 지운 뒤, device가 내용을 받아 가는 동안에는 writeback 상태가 남습니다. 그 사이 새 변경이 들어오면 dirty와 writeback이 동시에 설정될 수도 있습니다.
이 세부 상태는 writeback iterator와 filesystem callback 사이의 계약입니다. 여기서는 upstream v6.18의 folio 기반 구현을 중심으로 보고, 오래된 write_cache_pages()의 pagevec loop와 같은 코드라고 취급하지 않겠습니다.
writeback_control은 범위와 정책을 전달합니다
writeback_control의 range_start와 range_end는 byte 범위이며 끝은 inclusive입니다. nr_to_write는 목표로 삼는 base page 수이고 pages_skipped는 처리하지 못한 양을 기록합니다. 큰 folio 하나를 처리해도 counter를 하나만 줄이는 것은 아닙니다.
WB_SYNC_NONE은 background 작업처럼 진행 가능한 만큼 처리하는 정책입니다. WB_SYNC_ALL은 data-integrity 요구가 있는 작업이며 이미 진행 중인 writeback을 건너뛰거나 작은 quota만 채우고 끝내서는 안 됩니다. 그렇다고 이 flag 하나가 모든 filesystem callback 내부의 BIO 완료 대기를 자동으로 수행하지는 않습니다. 호출 계층에서 별도 wait가 필요할 수 있습니다.
for_kupdate는 주기적인 오래된 data 처리, for_background는 dirty threshold에 따른 처리를 구별합니다. 예전 구조체의 for_reclaim은 reclaim 목적을 나타냈지만 아래 v6.18 구조체에는 그 필드가 없습니다. tagged_writepages는 고정한 대상 집합을 사용하도록 하고, range_cyclic은 다음 검색 위치를 mapping->writeback_index로 이어 갑니다. for_sync는 전체 sync가 외부에서 기다리는 경로라는 의미도 가지므로 단순히 sync_mode의 별명은 아닙니다. v6.18 mm/page-writeback.c
다음은 v6.18 writeback_control 전체입니다. caller가 지정하는 공개 필드와 iterator가 사용하는 fbatch, index, saved_err를 나눠 볼 수 있습니다. unpinned_netfs_wb는 inode의 netfs writeback pin이 해제된 사실과 관계된 표시이지 지금 folio가 pinned라는 뜻이 아닙니다. no_cgroup_owner는 비동기 계층으로 넘긴 뒤의 단계가 최초 writeback과 같은 소유권 accounting을 반복하지 않도록 하는 조건입니다.
for_sync가 전달된 전체-sync work는 dirty-time 목록에도 그 work의 dirtied_before 경계를 사용합니다. 일반 work처럼 별도의 dirtytime 만료 간격을 빼서 오래된 timestamp만 고르는 것이 아닙니다. 개별 inode 처리에서도 바깥의 superblock sync가 기다리도록 대기 책임을 나눕니다. 그렇다고 sync_mode를 NONE으로 바꾸는 것은 아닙니다. quota만 채우고 종료하는지, 기존 writeback을 기다리는지와 최종 wait의 위치를 각각 구별해야 합니다. v6.18 queue와 inode 처리
struct_writeback_control_v6_18.h
// SPDX-License-Identifier: GPL-2.0
/*
 * Complete scope from Linux v6.18 include/linux/writeback.h.
 * Source: https://github.com/torvalds/linux/blob/v6.18/include/linux/writeback.h
 * Kernel excerpt; not a standalone program.
 * The book's exact source tag is not asserted.
 */

struct writeback_control {
	/* public fields that can be set and/or consumed by the caller: */
	long nr_to_write;		/* Write this many pages, and decrement
					   this for each page written */
	long pages_skipped;		/* Pages which were not written */

	/*
	 * For a_ops->writepages(): if start or end are non-zero then this is
	 * a hint that the filesystem need only write out the pages inside that
	 * byterange.  The byte at `end' is included in the writeout request.
	 */
	loff_t range_start;
	loff_t range_end;

	enum writeback_sync_modes sync_mode;

	unsigned for_kupdate:1;		/* A kupdate writeback */
	unsigned for_background:1;	/* A background writeback */
	unsigned tagged_writepages:1;	/* tag-and-write to avoid livelock */
	unsigned range_cyclic:1;	/* range_start is cyclic */
	unsigned for_sync:1;		/* sync(2) WB_SYNC_ALL writeback */
	unsigned unpinned_netfs_wb:1;	/* Cleared I_PINNING_NETFS_WB */

	/*
	 * When writeback IOs are bounced through async layers, only the
	 * initial synchronous phase should be accounted towards inode
	 * cgroup ownership arbitration to avoid confusion.  Later stages
	 * can set the following flag to disable the accounting.
	 */
	unsigned no_cgroup_owner:1;

	/* internal fields used by the ->writepages implementation: */
	struct folio_batch fbatch;
	pgoff_t index;
	int saved_err;

#ifdef CONFIG_CGROUP_WRITEBACK
	struct bdi_writeback *wb;	/* wb this writeback is issued under */
	struct inode *inode;		/* inode being written out */

	/* foreign inode detection, see wbc_detach_inode() */
	int wb_id;			/* current wb id */
	int wb_lcand_id;		/* last foreign candidate wb id */
	int wb_tcand_id;		/* this foreign candidate wb id */
	size_t wb_bytes;		/* bytes written by current wb */
	size_t wb_lcand_bytes;		/* bytes written by last candidate */
	size_t wb_tcand_bytes;		/* bytes written by this candidate */
#endif
};
TOWRITE는 계속 늘어나는 작업을 붙잡아 둡니다
파일의 앞부분을 저장하는 동안 뒷부분에 dirty folio가 계속 추가된다면, DIRTY mark를 끝없이 쫓는 loop는 끝나지 않을 수 있습니다. data-integrity 작업에서는 현재 dirty 대상을 먼저 PAGECACHE_TAG_TOWRITE로 표시하고 그 집합을 처리합니다.
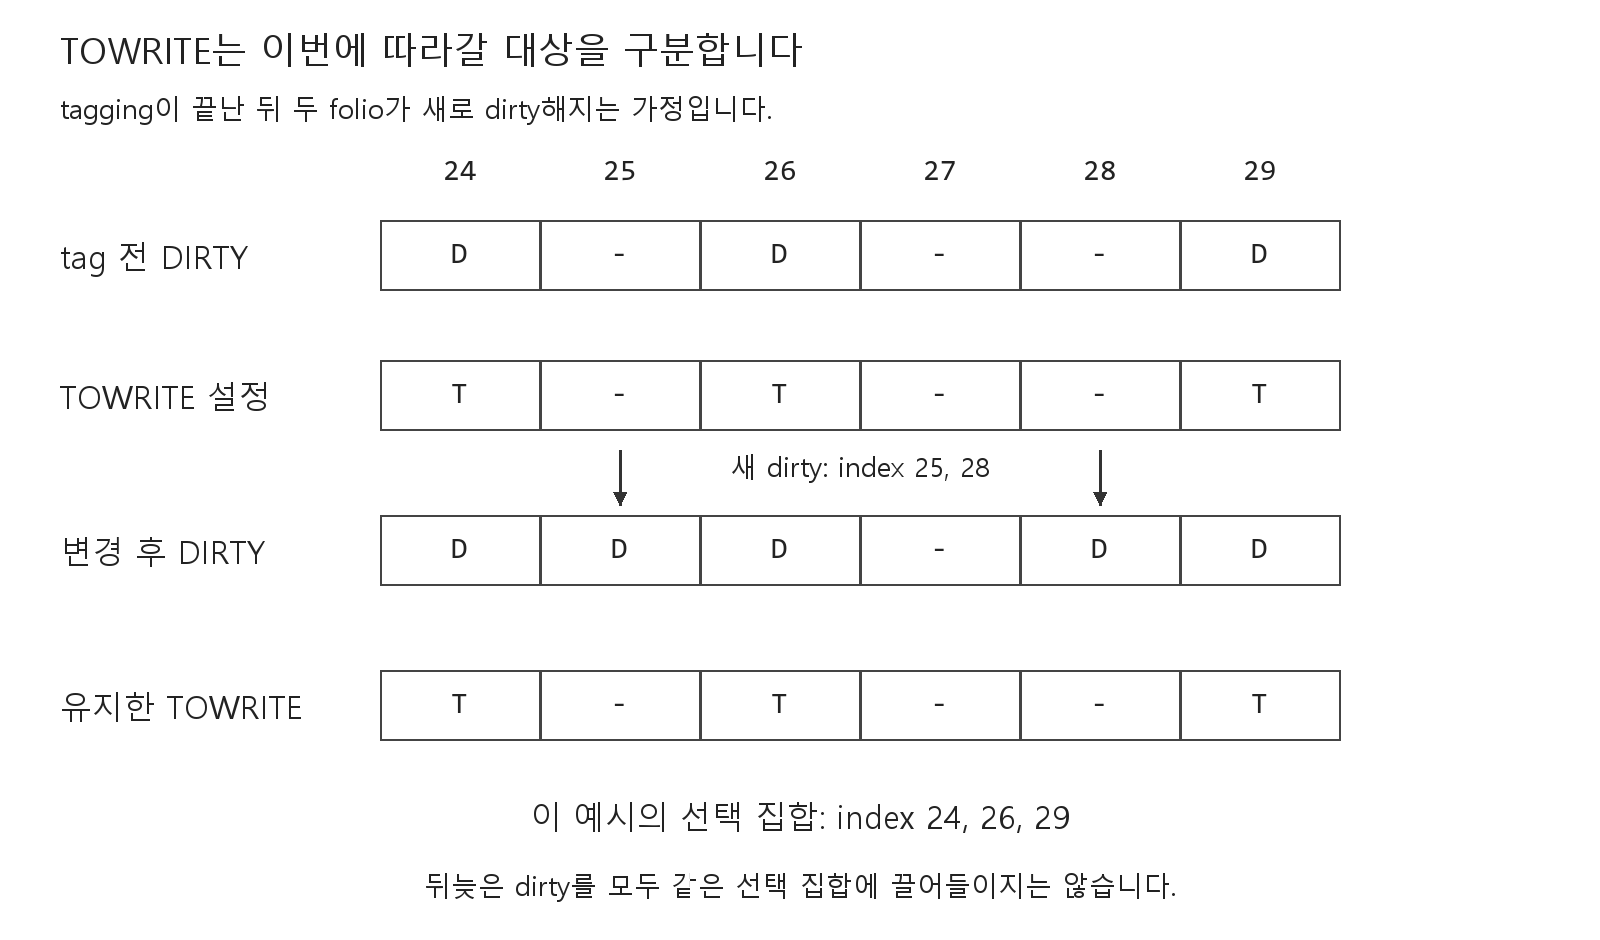
그림은 대상 선택과 이후 dirtying의 구분을 나타냅니다. concurrent truncate, filesystem별 I/O 병합과 error 처리는 생략했습니다.
tag_pages_for_writeback()은 XArray mark 검색으로 대상을 표시합니다. 오래 잡고 있으면 안 되는 lock은 검색 상태를 pause하고 reschedule한 뒤 다시 잡을 수 있습니다. 이 표시는 byte 내용의 snapshot을 복제하는 것이 아닙니다. 나중에 실제 folio를 잠갔을 때 상태를 다시 확인해야 합니다.
TOWRITE를 아무 경로에서나 지우지 않는 규칙도 중요합니다. data-integrity 작업이 선택한 folio를 다른 작업이 먼저 건드렸다는 이유로 검색에서 잃어서는 안 됩니다. DIRTY를 지우고 I/O로 넘기는 전환과 함께 정리해야 합니다.
lookup 뒤에는 folio lock 아래에서 다시 검사합니다
v6.18 folio_prepare_writeback()은 mapping이 여전히 같은지, dirty인지, 기존 writeback이 있는지를 확인합니다. truncate나 invalidate로 옛 mapping에서 빠진 folio라면 같은 index에 새 folio가 생겼더라도 이 pointer를 그 새 대상으로 취급하지 않습니다.
이미 writeback 중이면 WB_SYNC_NONE에서는 건너뛸 수 있지만 WB_SYNC_ALL에서는 종료를 기다립니다. dirty와 writeback이 함께 설정된 경우를 실제로 처리해야 하기 때문입니다. 그 뒤 folio_clear_dirty_for_io()가 이번 I/O에 넘길 dirty 전환을 수행합니다.
do_writepages()는 filesystem의 writepages callback을 호출하는 상위 진입점입니다. v6.18에서는 callback이 없는 특수 파일을 그냥 처리 없음으로 돌려보내며, 언제나 generic_writepages()로 fallback하는 오래된 설명과 다릅니다. -ENOMEM이고 WB_SYNC_ALL이면 reclaim 쪽 throttle을 거쳐 재시도할 수 있지만 일반 error를 모두 무한 재시도하지는 않습니다.
다음은 v6.18 전체 진입점입니다. 진입 시 nr_to_write <= 0이면 바로 0으로 반환합니다. integrity iterator가 진행 중 quota만으로 종료하지 않는다는 규칙을 이 초기 진입 조건까지 없다는 뜻으로 확대해서는 안 됩니다. caller도 적절한 work 목표를 준비해야 합니다.
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.18 mm/page-writeback.c.
 * Source: https://github.com/torvalds/linux/blob/v6.18/mm/page-writeback.c
 * Copyright (C) 2002, Linus Torvalds.
 * Copyright (C) 2007 Red Hat, Inc., Peter Zijlstra
 * 10Apr2002 Andrew Morton -- Initial version.
 * Kernel excerpt; not a standalone program.
 * The book's exact source tag is not asserted.
 */

int do_writepages(struct address_space *mapping, struct writeback_control *wbc)
{
	int ret;
	struct bdi_writeback *wb;

	if (wbc->nr_to_write <= 0)
		return 0;
	wb = inode_to_wb_wbc(mapping->host, wbc);
	wb_bandwidth_estimate_start(wb);
	while (1) {
		if (mapping->a_ops->writepages)
			ret = mapping->a_ops->writepages(mapping, wbc);
		else
			/* deal with chardevs and other special files */
			ret = 0;
		if (ret != -ENOMEM || wbc->sync_mode != WB_SYNC_ALL)
			break;

		/*
		 * Lacking an allocation context or the locality or writeback
		 * state of any of the inode's pages, throttle based on
		 * writeback activity on the local node. It's as good a
		 * guess as any.
		 */
		reclaim_throttle(NODE_DATA(numa_node_id()),
			VMSCAN_THROTTLE_WRITEBACK);
	}
	/*
	 * Usually few pages are written by now from those we've just submitted
	 * but if there's constant writeback being submitted, this makes sure
	 * writeback bandwidth is updated once in a while.
	 */
	if (time_is_before_jiffies(READ_ONCE(wb->bw_time_stamp) +
				   BANDWIDTH_INTERVAL))
		wb_update_bandwidth(wb);
	return ret;
}
이 함수는 wb의 bandwidth 측정 시작을 기록하고, 마지막 갱신 시점에 interval을 더한 시간이 이미 지났으면 wb_update_bandwidth()를 호출합니다. interval 안이면 갱신한다는 조건이 아닙니다. WB_SYNC_ALL이라는 인자만으로 callback이 반환하기 전에 모든 새 BIO를 각각 기다린다고 가정하지도 않습니다. 실제 folio 선택과 iterator는 다음 객체를 얻고 오류·참조를 마무리하는 경로를 별도로 다룹니다.
PTE를 보호한 뒤 folio dirty를 지웁니다
file-backed shared PTE가 writable이면 다음 store는 fault를 내지 않을 수 있습니다. folio_clear_dirty_for_io()는 필요한 경우 reverse mapping의 folio_mkclean()으로 해당 mapping을 clean·write-protect합니다. 이후 새 변경이 fault를 거쳐 다시 dirty로 추적되도록 만드는 것입니다.
이 함수는 folio lock 아래에서 동작하며 write fault 쪽의 folio dirty 처리도 이 lock과 맞물립니다. PTE를 clean하는 과정에서 발견한 dirty를 folio_mark_dirty()로 folio 상태에 다시 반영한 뒤 master dirty bit를 검사하고 지웁니다. accounting을 줄이는 것도 이 전환에 묶습니다.
이 순간에는 folio의 dirty bit와 XArray DIRTY mark가 잠시 다를 수 있습니다. helper는 folio dirty를 지우되 XArray mark를 즉시 지우지 않아 concurrent sync 검색이 대상을 잃지 않게 합니다. locked folio를 I/O로 넘기거나 redirty하는 후속 처리에서 둘을 맞춥니다. bit 하나가 항상 mark와 동일하다는 가정으로 중간 코드를 읽으면 이 설계가 모순처럼 보입니다.
다음은 v6.18 folio_clear_dirty_for_io() 전체입니다. writeback 가능한 mapping에서는 wb association을 안정적으로 사용해 dirty accounting을 내리고, 다른 경우에는 dirty bit의 test-and-clear 결과를 반환합니다. true는 이번에 dirty를 지웠다는 뜻이고 이미 clean이었다면 false입니다. 함수가 false라는 이유만으로 I/O가 성공했다고 판단하지 않습니다.
folio_clear_dirty_for_io_v6_18.c
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.18 mm/page-writeback.c.
 * Source: https://github.com/torvalds/linux/blob/v6.18/mm/page-writeback.c
 * Copyright (C) 2002, Linus Torvalds.
 * Copyright (C) 2007 Red Hat, Inc., Peter Zijlstra
 * 10Apr2002 Andrew Morton -- Initial version.
 * Kernel excerpt; not a standalone program.
 * The book's exact source tag is not asserted.
 */

bool folio_clear_dirty_for_io(struct folio *folio)
{
	struct address_space *mapping = folio_mapping(folio);
	bool ret = false;

	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);

	if (mapping && mapping_can_writeback(mapping)) {
		struct inode *inode = mapping->host;
		struct bdi_writeback *wb;
		struct wb_lock_cookie cookie = {};

		/*
		 * Yes, Virginia, this is indeed insane.
		 *
		 * We use this sequence to make sure that
		 *  (a) we account for dirty stats properly
		 *  (b) we tell the low-level filesystem to
		 *      mark the whole folio dirty if it was
		 *      dirty in a pagetable. Only to then
		 *  (c) clean the folio again and return 1 to
		 *      cause the writeback.
		 *
		 * This way we avoid all nasty races with the
		 * dirty bit in multiple places and clearing
		 * them concurrently from different threads.
		 *
		 * Note! Normally the "folio_mark_dirty(folio)"
		 * has no effect on the actual dirty bit - since
		 * that will already usually be set. But we
		 * need the side effects, and it can help us
		 * avoid races.
		 *
		 * We basically use the folio "master dirty bit"
		 * as a serialization point for all the different
		 * threads doing their things.
		 */
		if (folio_mkclean(folio))
			folio_mark_dirty(folio);
		/*
		 * We carefully synchronise fault handlers against
		 * installing a dirty pte and marking the folio dirty
		 * at this point.  We do this by having them hold the
		 * page lock while dirtying the folio, and folios are
		 * always locked coming in here, so we get the desired
		 * exclusion.
		 */
		wb = unlocked_inode_to_wb_begin(inode, &cookie);
		if (folio_test_clear_dirty(folio)) {
			long nr = folio_nr_pages(folio);
			lruvec_stat_mod_folio(folio, NR_FILE_DIRTY, -nr);
			zone_stat_mod_folio(folio, NR_ZONE_WRITE_PENDING, -nr);
			wb_stat_mod(wb, WB_RECLAIMABLE, -nr);
			ret = true;
		}
		unlocked_inode_to_wb_end(inode, &cookie);
		return ret;
	}
	return folio_test_clear_dirty(folio);
}
writeback 시작과 완료는 별도로 추적합니다
__folio_start_writeback()은 locked folio가 아직 writeback 중이 아니라는 전제를 검사합니다. XArray를 사용하는 mapping에서는 WRITEBACK mark를 세우고 WB_WRITEBACK을 증가시킵니다. mapping에서 처음 writeback이 시작되었다면 inode의 진행 중 writeback 추적도 연결합니다.
새 변경으로 folio가 다시 dirty가 아니라면 DIRTY mark를 정리합니다. 일반 경로에서는 TOWRITE도 지우지만 keep_write 같은 별도 요청에 따라 남길 수 있습니다. 이 상태 변화가 I/O 완료를 뜻하지는 않습니다.
현재 시작 함수 전체에는 mapping이 writeback tag를 사용하지 않는 대안 경로와 node·zone 통계, architecture 접근 가능성 검사까지 들어 있습니다. architecture가 접근 가능하게 만들 수 없는 folio에서 이미 writeback을 시작했다면 여기서는 일반 errno로 복구하는 것이 아니라 debug assertion으로 드러내는 계약입니다.
__folio_start_writeback_v6_18.c
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.18 mm/page-writeback.c.
 * Source: https://github.com/torvalds/linux/blob/v6.18/mm/page-writeback.c
 * Copyright (C) 2002, Linus Torvalds.
 * Copyright (C) 2007 Red Hat, Inc., Peter Zijlstra
 * 10Apr2002 Andrew Morton -- Initial version.
 * Kernel excerpt; not a standalone program.
 * The book's exact source tag is not asserted.
 */

void __folio_start_writeback(struct folio *folio, bool keep_write)
{
	long nr = folio_nr_pages(folio);
	struct address_space *mapping = folio_mapping(folio);
	int access_ret;

	VM_BUG_ON_FOLIO(folio_test_writeback(folio), folio);
	VM_BUG_ON_FOLIO(!folio_test_locked(folio), folio);

	if (mapping && mapping_use_writeback_tags(mapping)) {
		XA_STATE(xas, &mapping->i_pages, folio->index);
		struct inode *inode = mapping->host;
		struct bdi_writeback *wb;
		unsigned long flags;
		bool on_wblist;

		xas_lock_irqsave(&xas, flags);
		xas_load(&xas);
		folio_test_set_writeback(folio);

		on_wblist = mapping_tagged(mapping, PAGECACHE_TAG_WRITEBACK);

		xas_set_mark(&xas, PAGECACHE_TAG_WRITEBACK);
		wb = inode_to_wb(inode);
		wb_stat_mod(wb, WB_WRITEBACK, nr);
		if (!on_wblist) {
			wb_inode_writeback_start(wb);
			/*
			 * We can come through here when swapping anonymous
			 * folios, so we don't necessarily have an inode to
			 * track for sync.
			 */
			if (mapping->host)
				sb_mark_inode_writeback(mapping->host);
		}

		if (!folio_test_dirty(folio))
			xas_clear_mark(&xas, PAGECACHE_TAG_DIRTY);
		if (!keep_write)
			xas_clear_mark(&xas, PAGECACHE_TAG_TOWRITE);
		xas_unlock_irqrestore(&xas, flags);
	} else {
		folio_test_set_writeback(folio);
	}

	lruvec_stat_mod_folio(folio, NR_WRITEBACK, nr);
	zone_stat_mod_folio(folio, NR_ZONE_WRITE_PENDING, nr);

	access_ret = arch_make_folio_accessible(folio);
	/*
	 * If writeback has been triggered on a page that cannot be made
	 * accessible, it is too late to recover here.
	 */
	VM_BUG_ON_FOLIO(access_ret != 0, folio);
}
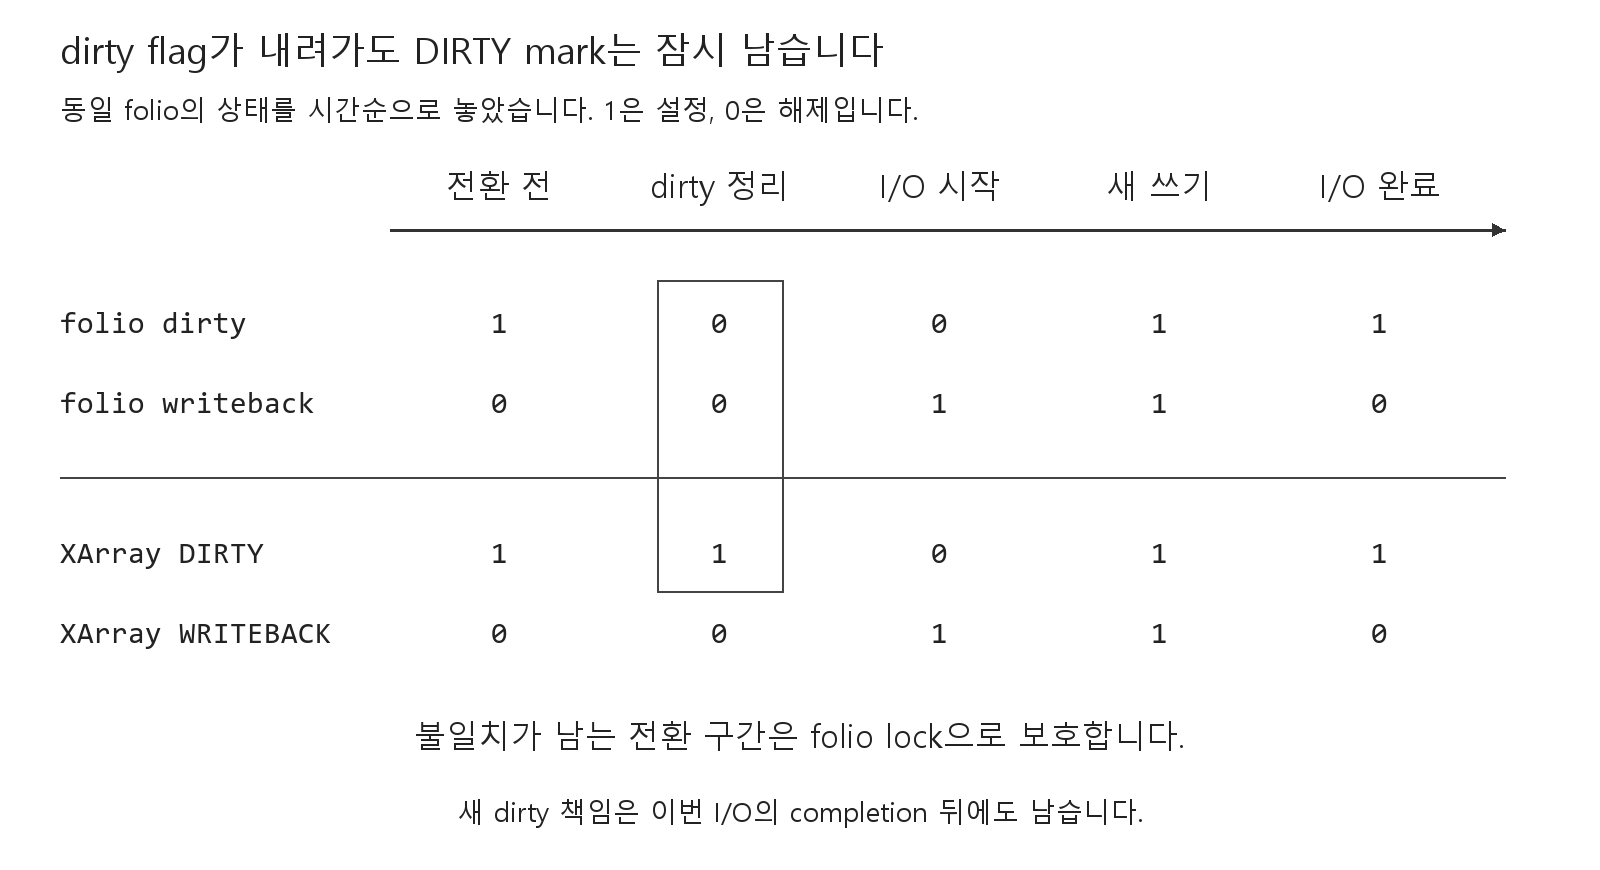
그림은 folio bit와 XArray mark가 변하는 순서를 함께 나타냅니다. dirty를 지웠지만 DIRTY mark는 남아 있는 구간도 표시했습니다. 실제 I/O 내용, error 기록과 실패 후 재시도 정책은 생략했습니다.
완료 쪽 __folio_end_writeback()은 WRITEBACK mark와 bit, 진행량 통계를 정리합니다. mapping의 마지막 writeback이 끝나면 inode 추적을 해제하고 wb·domain의 writeout 완료량을 갱신합니다. 이 현재 함수 자체를 지연 bandwidth work를 예약하는 helper라고 설명하지 않습니다. 상위 완료 처리는 waiter를 깨웁니다. 이때 별도로 다시 설정된 dirty까지 무조건 지우면 새 변경을 잃으므로, 완료를 clean 선언과 동일시해서는 안 됩니다.
아래는 현재 완료 내부 함수와 상위 함수 둘의 전체입니다. __folio_end_writeback()의 bool은 I/O 성공 여부가 아니라 waiter 깨우기 판단에 쓰입니다. 실제 I/O 오류의 기록은 별도 경로의 책임입니다. folio_end_writeback_no_dropbehind()는 reclaim 상태를 정리하고 필요한 waiter를 깨웁니다.
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.18 mm/page-writeback.c.
 * Source: https://github.com/torvalds/linux/blob/v6.18/mm/page-writeback.c
 * Copyright (C) 2002, Linus Torvalds.
 * Copyright (C) 2007 Red Hat, Inc., Peter Zijlstra
 * 10Apr2002 Andrew Morton -- Initial version.
 * Kernel excerpt; not a standalone program.
 * The book's exact source tag is not asserted.
 */

bool __folio_end_writeback(struct folio *folio)
{
	long nr = folio_nr_pages(folio);
	struct address_space *mapping = folio_mapping(folio);
	bool ret;

	if (mapping && mapping_use_writeback_tags(mapping)) {
		struct inode *inode = mapping->host;
		struct bdi_writeback *wb;
		unsigned long flags;

		xa_lock_irqsave(&mapping->i_pages, flags);
		ret = folio_xor_flags_has_waiters(folio, 1 << PG_writeback);
		__xa_clear_mark(&mapping->i_pages, folio->index,
					PAGECACHE_TAG_WRITEBACK);

		wb = inode_to_wb(inode);
		wb_stat_mod(wb, WB_WRITEBACK, -nr);
		__wb_writeout_add(wb, nr);
		if (!mapping_tagged(mapping, PAGECACHE_TAG_WRITEBACK)) {
			wb_inode_writeback_end(wb);
			if (mapping->host)
				sb_clear_inode_writeback(mapping->host);
		}

		xa_unlock_irqrestore(&mapping->i_pages, flags);
	} else {
		ret = folio_xor_flags_has_waiters(folio, 1 << PG_writeback);
	}

	lruvec_stat_mod_folio(folio, NR_WRITEBACK, -nr);
	zone_stat_mod_folio(folio, NR_ZONE_WRITE_PENDING, -nr);
	node_stat_mod_folio(folio, NR_WRITTEN, nr);

	return ret;
}
folio_end_writeback_no_dropbehind_v6_18.c
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.18 mm/filemap.c.
 * Source: https://github.com/torvalds/linux/blob/v6.18/mm/filemap.c
 * Copyright (C) 1994-1999  Linus Torvalds
 * Kernel excerpt; not a standalone program.
 * The book's exact source tag is not asserted.
 */

void folio_end_writeback_no_dropbehind(struct folio *folio)
{
	VM_BUG_ON_FOLIO(!folio_test_writeback(folio), folio);

	/*
	 * folio_test_clear_reclaim() could be used here but it is an
	 * atomic operation and overkill in this particular case. Failing
	 * to shuffle a folio marked for immediate reclaim is too mild
	 * a gain to justify taking an atomic operation penalty at the
	 * end of every folio writeback.
	 */
	if (folio_test_reclaim(folio)) {
		folio_clear_reclaim(folio);
		folio_rotate_reclaimable(folio);
	}

	if (__folio_end_writeback(folio))
		folio_wake_bit(folio, PG_writeback);

	acct_reclaim_writeback(folio);
}
일반 folio_end_writeback()은 완료 처리와 dropbehind 동안 folio가 해제·재사용되지 않도록 임시 참조를 얻고 마지막에 놓습니다. writeback bit 자체가 독립적인 folio 참조 하나를 영구히 소유하는 구조라고 세면 안 됩니다. writeback 동안 truncate가 종료를 기다리는 계약과 완료 중 wakeup의 짧은 수명 보호를 구별해야 합니다.
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.18 mm/filemap.c.
 * Source: https://github.com/torvalds/linux/blob/v6.18/mm/filemap.c
 * Copyright (C) 1994-1999  Linus Torvalds
 * Kernel excerpt; not a standalone program.
 * The book's exact source tag is not asserted.
 */

void folio_end_writeback(struct folio *folio)
{
	VM_BUG_ON_FOLIO(!folio_test_writeback(folio), folio);

	/*
	 * Writeback does not hold a folio reference of its own, relying
	 * on truncation to wait for the clearing of PG_writeback.
	 * But here we must make sure that the folio is not freed and
	 * reused before the folio_wake_bit().
	 */
	folio_get(folio);
	folio_end_writeback_no_dropbehind(folio);
	folio_end_dropbehind(folio);
	folio_put(folio);
}
예전 bool 반환값은 I/O 성공 여부가 아닙니다
다음은 Linux v6.0 __folio_start_writeback()과 __folio_end_writeback() 전체입니다. 앞의 현재 구현과 비교하기 위한 source이며, 책이 정확히 이 tag를 사용했다고 단정하지 않습니다. 두 함수 모두 당시의 accounting, tag를 쓰지 않는 경로와 architecture 검사를 생략하지 않았습니다.
__folio_start_writeback_v6_0.c
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.0 mm/page-writeback.c.
 * Source: https://github.com/torvalds/linux/blob/v6.0/mm/page-writeback.c
 * Kernel excerpt; not a standalone program.
 * The book exact source tag is not asserted.
 */

/*
 * mm/page-writeback.c
 *
 * Copyright (C) 2002, Linus Torvalds.
 * Copyright (C) 2007 Red Hat, Inc., Peter Zijlstra
 *
 * Contains functions related to writing back dirty pages at the
 * address_space level.
 *
 * 10Apr2002	Andrew Morton
 *		Initial version
 */

bool __folio_start_writeback(struct folio *folio, bool keep_write)
{
	long nr = folio_nr_pages(folio);
	struct address_space *mapping = folio_mapping(folio);
	bool ret;
	int access_ret;

	folio_memcg_lock(folio);
	if (mapping && mapping_use_writeback_tags(mapping)) {
		XA_STATE(xas, &mapping->i_pages, folio_index(folio));
		struct inode *inode = mapping->host;
		struct backing_dev_info *bdi = inode_to_bdi(inode);
		unsigned long flags;

		xas_lock_irqsave(&xas, flags);
		xas_load(&xas);
		ret = folio_test_set_writeback(folio);
		if (!ret) {
			bool on_wblist;

			on_wblist = mapping_tagged(mapping,
						   PAGECACHE_TAG_WRITEBACK);

			xas_set_mark(&xas, PAGECACHE_TAG_WRITEBACK);
			if (bdi->capabilities & BDI_CAP_WRITEBACK_ACCT) {
				struct bdi_writeback *wb = inode_to_wb(inode);

				wb_stat_mod(wb, WB_WRITEBACK, nr);
				if (!on_wblist)
					wb_inode_writeback_start(wb);
			}

			/*
			 * We can come through here when swapping
			 * anonymous folios, so we don't necessarily
			 * have an inode to track for sync.
			 */
			if (mapping->host && !on_wblist)
				sb_mark_inode_writeback(mapping->host);
		}
		if (!folio_test_dirty(folio))
			xas_clear_mark(&xas, PAGECACHE_TAG_DIRTY);
		if (!keep_write)
			xas_clear_mark(&xas, PAGECACHE_TAG_TOWRITE);
		xas_unlock_irqrestore(&xas, flags);
	} else {
		ret = folio_test_set_writeback(folio);
	}
	if (!ret) {
		lruvec_stat_mod_folio(folio, NR_WRITEBACK, nr);
		zone_stat_mod_folio(folio, NR_ZONE_WRITE_PENDING, nr);
	}
	folio_memcg_unlock(folio);
	access_ret = arch_make_folio_accessible(folio);
	/*
	 * If writeback has been triggered on a page that cannot be made
	 * accessible, it is too late to recover here.
	 */
	VM_BUG_ON_FOLIO(access_ret != 0, folio);

	return ret;
}
// SPDX-License-Identifier: GPL-2.0-only
/*
 * Complete scope from Linux v6.0 mm/page-writeback.c.
 * Source: https://github.com/torvalds/linux/blob/v6.0/mm/page-writeback.c
 * Kernel excerpt; not a standalone program.
 * The book exact source tag is not asserted.
 */

/*
 * mm/page-writeback.c
 *
 * Copyright (C) 2002, Linus Torvalds.
 * Copyright (C) 2007 Red Hat, Inc., Peter Zijlstra
 *
 * Contains functions related to writing back dirty pages at the
 * address_space level.
 *
 * 10Apr2002	Andrew Morton
 *		Initial version
 */

bool __folio_end_writeback(struct folio *folio)
{
	long nr = folio_nr_pages(folio);
	struct address_space *mapping = folio_mapping(folio);
	bool ret;

	folio_memcg_lock(folio);
	if (mapping && mapping_use_writeback_tags(mapping)) {
		struct inode *inode = mapping->host;
		struct backing_dev_info *bdi = inode_to_bdi(inode);
		unsigned long flags;

		xa_lock_irqsave(&mapping->i_pages, flags);
		ret = folio_test_clear_writeback(folio);
		if (ret) {
			__xa_clear_mark(&mapping->i_pages, folio_index(folio),
						PAGECACHE_TAG_WRITEBACK);
			if (bdi->capabilities & BDI_CAP_WRITEBACK_ACCT) {
				struct bdi_writeback *wb = inode_to_wb(inode);

				wb_stat_mod(wb, WB_WRITEBACK, -nr);
				__wb_writeout_add(wb, nr);
				if (!mapping_tagged(mapping,
						    PAGECACHE_TAG_WRITEBACK))
					wb_inode_writeback_end(wb);
			}
		}

		if (mapping->host && !mapping_tagged(mapping,
						     PAGECACHE_TAG_WRITEBACK))
			sb_clear_inode_writeback(mapping->host);

		xa_unlock_irqrestore(&mapping->i_pages, flags);
	} else {
		ret = folio_test_clear_writeback(folio);
	}
	if (ret) {
		lruvec_stat_mod_folio(folio, NR_WRITEBACK, -nr);
		zone_stat_mod_folio(folio, NR_ZONE_WRITE_PENDING, -nr);
		node_stat_mod_folio(folio, NR_WRITTEN, nr);
	}
	folio_memcg_unlock(folio);
	return ret;
}
v6.0 시작 함수의 bool은 folio_test_set_writeback()이 돌려준 이전 bit 상태입니다. I/O를 성공적으로 제출했다는 반환값이 아닙니다. v6.18 시작 함수는 void이며, 이미 writeback인 folio나 unlocked folio를 넘기지 않는 계약을 debug 검사로 드러냅니다. v6.0 완료 함수의 bool도 이전 writeback bit를 지웠는지를 나타내므로, 현재 내부 완료 함수의 waiter 판단용 bool과 의미를 바꾸어 읽지 않습니다.
두 버전 모두 writeback 시작 시 DIRTY mark를 지울지는 현재 folio dirty 상태에 달려 있습니다. 완료에서 새 dirty까지 지우는 대칭 연산을 하지 않습니다. keep_write에 따라 TOWRITE를 남기는 조건도 있으므로 모든 mark를 무조건 지운다는 설명은 성립하지 않습니다. 위 kernel code는 원본 파일의 GPL-2.0 license를 따르며 독립 compile 예제는 아닙니다.
iterator의 종료도 무조건 첫 index로 되돌아가지는 않습니다
v6.18 writeback_iter()는 이전 folio의 처리 결과를 받아 quota와 error를 정리하고 다음 folio를 돌려줍니다. background 작업은 quota 소진이나 error에 끝날 수 있습니다. integrity 작업은 첫 error를 보관하면서 이미 선택한 folio들의 정리가 계속될 수 있습니다.
cyclic 검색도 한 호출 안에서 끝까지 갔다가 즉시 파일 처음으로 돌아가는 단순 원형 loop가 아닙니다. 여러 folio를 묶어 I/O를 만드는 caller와 lock·writeback 순서가 역전되지 않도록, 끝에 도달하면 다음 호출의 시작 위치를 0으로 남기고 종료합니다. quota 때문에 끝났다면 마지막 처리 folio의 다음 index를 저장합니다.
오래된 pagevec 코드에 등장하는 AOP_WRITEPAGE_ACTIVATE 역시 성공적인 I/O 완료를 나타내는 일반 error code가 아닙니다. writepage가 진행을 거절하며 caller 쪽 unlock 처리가 필요한 특별한 계약입니다. 현대 filesystem을 볼 때에는 예전 loop의 local 분기를 그대로 찾기보다 현재 writepages와 folio iterator의 책임을 확인해야 합니다.
참고 자료
- Lorenzo Stoakes, The Linux Memory Manager, Early Access 2025, Chapter 10, Writing Back to Disk의 writeback_control, scan 및 dirty 정리 설명.
- Linux v6.18 mm/page-writeback.c:
writeback_iter(),folio_prepare_writeback(), dirty와 writeback 상태 전환. - Linux v6.18 include/linux/writeback.h: writeback 제어 interface.